POEMED and the Competition: A Head-to-Head
Source:vignettes/poemed-vs-competitors.Rmd
poemed-vs-competitors.RmdThe established test for whether any of many candidate mediators is active is the total-indirect-effect Wald test of Guo et al. (2022), which this package reports as HDMM. POEMED’s power-enhanced test (PE) keeps that test intact and adds a component that reads the marginal signal from individual mediators. The two therefore agree by construction whenever the enhancement is zero, and differ only when it is not.
Under the global null the enhancement is built to vanish, so as the
sample size and the number of candidate mediators grow, the
power-enhanced test’s size approaches the nominal level, as the
benchmark’s does, by Theorem 1 of Yu and Kelley (in press). In finite
samples it rejects slightly more often than the benchmark. When the
active mediators all push the outcome the same way, both tests gain
power and the enhancement adds a margin (the article’s Figure 3(a));
that homogeneous case is the easy one, and it is not the one that
motivates the method. The cases that do, mediators acting in different
directions, are where the benchmark loses most of its power and the
power-enhanced test keeps more of its own. This vignette leads with
those, then shows the homogeneous case, and lets the output speak
throughout. (The article also compares HILMA, GlobalTest, HDMT, and
DACT, which live in separate packages; the closing section shows how to
run HILMA and GlobalTest beside a POEMED fit and where to find HDMT and
DACT.) Every study in this vignette passes the same tuning grid to
lambda_grid, 20 values from 0.05 to 2, because a simulation
study fits hundreds of models and a shorter grid than the package
default of 100 values makes each fit several times faster; whatever the
grid, each fit keeps the best value the grid offers.
Two Patterns of Mediation, Two Tests
Consider two designs with the same exposure, number of mediators,
sample size, and signal strength (c1 = 1). In the first,
the active mediators all push the outcome the same way
(homogeneous). In the second, they push in opposite
directions and exactly cancel, so the total indirect effect is zero even
though four mediators are truly active (contrasting).
Any one simulated data set can land either way, so the chunk below draws
20 data sets of each kind and reports how often each test rejects at the
0.05 level.
lead <- pe_simulation_study(n = 200, p = 60, outcome = "continuous",
                            c1_grid = 1, n_rep = 20, lambda_grid = grid20)
lead
#>  pattern     c1 rejection_hdmm rejection_pe n_valid n_empty
#>  homogeneous 1  1              1            20      0
#>  contrasting 1  0.05           1            20      0
#>
#> Outcome: continuous
When the mediators agree in sign, the benchmark rejects at a rate of 1.00 and the power-enhanced test at 1.00. When they cancel, the benchmark’s rate falls to 0.05, while the power-enhanced test still rejects at 1.00. With 20 data sets each rate carries a Monte Carlo standard error of up to 0.11. The benchmark is not blind to every contrasting data set: a penalized fit that keeps only some of the canceling mediators can estimate a total indirect effect away from zero, and the benchmark can then reject. Both designs contain real mediation, and when the mediators cancel the power-enhanced test detects it far more often than the benchmark does.
Size Under the Global Null
A fair comparison starts at the null. With no active mediator
(c1 = 0) a test at the 0.05 level should reject about 5% of
the time. The enhancement is built to vanish under the null: as the
sample size and the number of candidate mediators grow, the screen flags
no mediator with probability tending to one, and the power-enhanced test
then reduces to the benchmark, by Theorem 1 of Yu and Kelley (in press).
In a finite sample the screen occasionally flags a mediator, so the
power-enhanced test rejects slightly more often than the benchmark. The
article’s own tables show this in every setting they report. At
n = 300 and p = 500 the power-enhanced test’s
size is 0.051 against the benchmark’s 0.037 when the mediators agree in
sign, and 0.044 against 0.036 when they cancel (supplement Table S.4).
At n = 50 with mediators that agree in sign it runs from
0.069 to 0.078, against the benchmark’s 0.047 to 0.061.
size <- pe_power_curve(n = 150, p = 50, outcome = "continuous",
                       pattern = "contrasting", c1_grid = 0, n_rep = 40,
                       lambda_grid = grid20)
size[, c("rejection_hdmm", "rejection_pe")]
#>  rejection_hdmm rejection_pe
#>  0.025          0.075
#>
#> Outcome: continuous
In this run the rejection rates are 0.025 for the benchmark and 0.075 for the power-enhanced test, from 40 null data sets. With 40 replications a rate near 0.05 carries a Monte Carlo standard error of about 0.03, so a run this short can tell a size near 0.05 from one near 0.15, but not 0.04 from 0.06. At the article’s design the size difference is about one percentage point, far smaller than the power differences in the sections that follow, so the power-enhanced test’s gains do not come from a looser null.
Power Where It Counts: Heterogeneous Mediation
A signal-strength sweep makes the gap visible. The shared helper below draws the benchmark and the power-enhanced rejection rates on one plot.
draw <- function(pc, main) {
  plot(pc$c1, pc$rejection_pe, type = "b", pch = 19, ylim = c(0, 1),
       xlab = expression(c[1]), ylab = "rejection rate", main = main)
  lines(pc$c1, pc$rejection_hdmm, type = "b", pch = 1, lty = 2)
  abline(h = 0.05, col = "grey60", lty = 3)
  legend("topleft", c("PE", "HDMM"), pch = c(19, 1), lty = c(1, 2), bty = "n")
}
grid <- c(0, 0.5, 1)
Two heterogeneous settings, both realistic. On the left, the active mediators fully cancel (the total indirect effect is exactly zero). On the right, six mediators of mixed sign only partially cancel, leaving a small nonzero total indirect effect, the kind of messy signal real data actually presents. In both, the power-enhanced test rejects at least as often as the benchmark, because its statistic adds a nonnegative component to the benchmark’s and uses the same reference distribution; the question is by how much.
p <- 50
# Mixed-sign mediators that only partially cancel: a small but nonzero total
# indirect effect, where the benchmark is weak and the enhancement is not.
alpha_mix <- c(1, -0.9, 0.8, -0.7, 0.6, -0.5, rep(0, p - 6))
tau_mix   <- c(rep(0.3, 6), rep(0, p - 6))

pc_cancel <- pe_power_curve(n = 150, p = p, outcome = "continuous",
                            pattern = "contrasting", c1_grid = grid, n_rep = 20,
                            lambda_grid = grid20)
pc_mixed  <- pe_power_curve(n = 150, p = p, outcome = "continuous",
                            c1_grid = grid, n_rep = 20, lambda_grid = grid20,
                            outcome_args = list(alpha_m = alpha_mix, tau = tau_mix))

op <- par(mfrow = c(1, 2))
draw(pc_cancel, "fully canceling")
draw(pc_mixed, "partially canceling")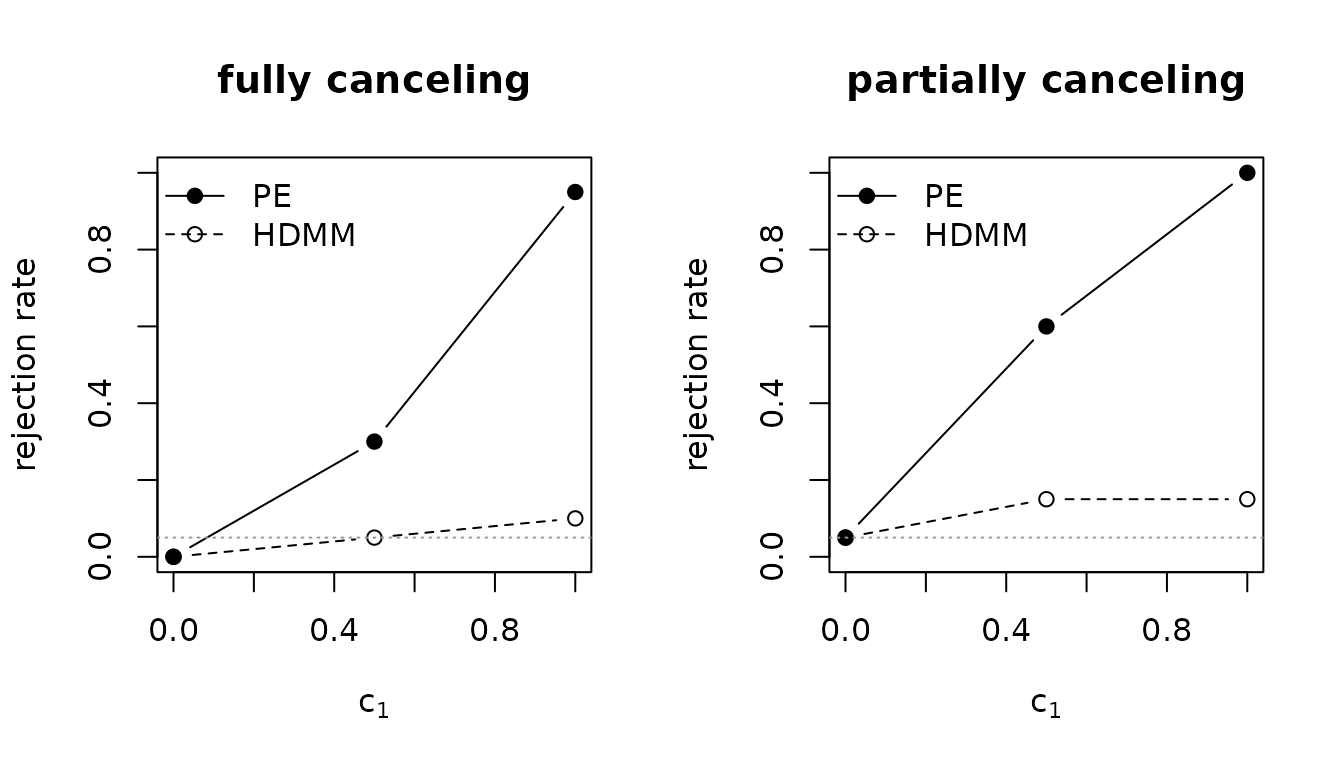
par(op)At c1 = 1 the benchmark and the power-enhanced test
reject at rates of 0.10 and 0.95 (fully canceling) and 0.15 and 1.00
(partially canceling), from 20 replications, so each carries a Monte
Carlo standard error of up to 0.11. The benchmark is built on the total
indirect effect; when that quantity is small or zero despite active
mediators, it has little to detect. The power-enhanced test reads the
individual mediators directly. When the mediators fully cancel, the
benchmark has almost nothing to detect and the power-enhanced test
rejects in nearly every data set; when they only partially cancel, the
benchmark recovers a little and the power-enhanced test still pulls far
ahead. Figure 3(b) of Yu and Kelley (in press) shows the same gap at the
article’s design (n = 300, p = 500) at
c1 = 1.
Homogeneous Mediation: Both Tests Work, and the Enhancement Still Helps
The easy case. When every active mediator pushes the same way, the total indirect effect grows with the signal and so does the benchmark’s power; the enhancement adds a margin rather than a rescue:
pc_homo <- pe_power_curve(n = 150, p = p, outcome = "continuous",
                          pattern = "homogeneous", c1_grid = grid, n_rep = 20,
                          lambda_grid = grid20)
draw(pc_homo, "homogeneous")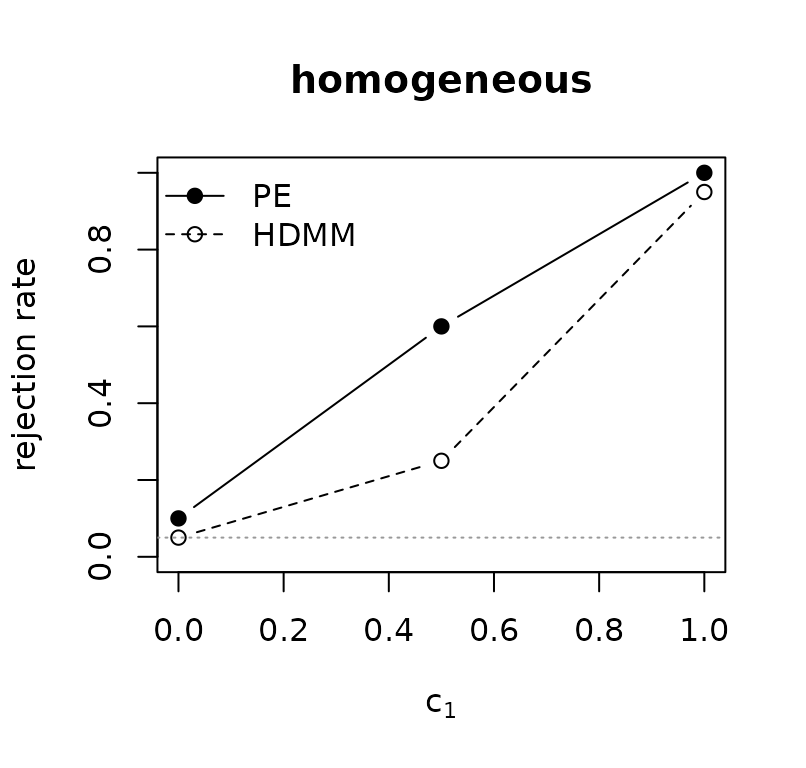
At c1 = 0.5 the benchmark rejects in 25 percent of
replications and the power-enhanced test in 60 percent. At the article’s
design, supplement Table S.4 gives 0.690 against 0.940 at that signal
strength. This is the honest boundary of the claim: where the benchmark
is already strong POEMED adds a margin, and where the benchmark is weak
it pulls away.
The Pattern Holds for Binary and Count Outcomes
The enhancement is not particular to continuous outcomes. Here is the
rejection rate at a fixed contrasting signal (c1 = 1) for
all three outcome models, from 20 replications each (a Monte Carlo
standard error of up to 0.11):
at_c1 <- function(outcome, c2) {
  pc <- pe_power_curve(n = 180, p = 50, outcome = outcome,
                       pattern = "contrasting", c1_grid = 1, c2 = c2,
                       n_rep = 20, lambda_grid = grid20)
  c(HDMM = pc$rejection_hdmm, PE = pc$rejection_pe)
}
round(rbind(continuous = at_c1("continuous", 0.5),
            binary     = at_c1("binary", 1),
            count      = at_c1("count", 0.4)), 3)
#>            HDMM  PE
#> continuous 0.00 1.0
#> binary     0.05 0.5
#> count      0.00 1.0
In each outcome model the power-enhanced test rejects more often than the benchmark.
Beyond a Yes/No: Which Mediators?
The benchmark answers one global question. The power-enhanced screen also identifies which mediators are active. The chunk below scores the active mediators it identifies over repeated contrasting data sets: the familywise error rate (how often any mediator that is not truly active is identified as active), and precision and recall against the truly active mediators.
id <- pe_identification_study(n = 150, p = 60, outcome = "continuous",
                              pattern = "contrasting", c1_grid = c(0, 1),
                              n_rep = 20, methods = "Bonferroni",
                              lambda_grid = grid20)
id
#>  c1 method     fwer fdr precision recall n_valid n_empty
#>  0  Bonferroni 0    0   0         0      20      0
#>  1  Bonferroni 0    0   1         0.5    20      0
#>
#> Outcome: continuous
The familywise error rate is 0.000 at the null and 0.000 at
c1 = 1. Precision and recall at c1 = 1 are
1.000 and 0.500 (20 replications, so each rate carries a Monte Carlo
standard error of up to 0.11). A longer run of the same design, the call
below with 400 replications, gave a familywise error rate of 0.0275 at
c1 = 1 (11 of the 400 data sets), under the 0.05 target,
with precision 0.9179 and recall 0.455. The screen’s control of that
rate is asymptotic, and in finite samples the rate depends on the tuning
grid as well as on the design: a grid that reaches small values of
lambda lets more candidates into the penalized fit, which
raises recall and can let a mediator that is not truly active through.
On a narrower grid, 20 values from 0.2 to 0.39 (the grid of the
article’s linear simulations), the same 400-replication run gave a
familywise error rate of 0 with precision 0.4525 and recall 0.1306. At
the article’s design and on that grid, supplement Table S.2 prints, for
the contrasting setting at c1 = 0.6, a familywise error
rate of 0.000 with precision 0.403 and recall 0.122.
# The longer runs quoted above (a seeded run with cores above 1 repeats
# exactly at the same number of cores).
long <- lapply(list(grid20, seq(0.2, 0.39, length.out = 20)), function(g)
  pe_identification_study(n = 150, p = 60, outcome = "continuous",
                          pattern = "contrasting", c1_grid = c(0, 1),
                          n_rep = 400, methods = "Bonferroni",
                          lambda_grid = g, cores = 4, seed = 113))
The benchmark offers no comparable list, because a test of whether the total indirect effect is zero does not point to any mediator.
On Real Data
The contrast is not only a simulation artifact. On the shipped WHO
health-expenditure data, summary() reports, group by group,
where the power-enhanced test finds mediation the benchmark does
not:
imr <- WHO_mediation_analysis("imr", groupings = c("global", "region", "income"))
imr_summary <- summary(imr)
imr_summary
#> POEMED comparison: IMR
#>   groups: 11 (11 with data), alpha_level = 0.05
#>   detected by benchmark (HDMM): 3   by power-enhanced (PE): 7
#>   PE detects mediation in 4 groups the benchmark misses:
#>  group n_countries pval_hdmm  pval_pe active_mediators
#>    ALL          91    0.0644 < 0.0001          gge_gdp
#>   SEAR           5    0.6483 < 0.0001   ext_usd2021_pc
#>    WPR           9    0.8681 < 0.0001          chi_che
#>    Low          16    0.3091 < 0.0001     pvtd_usd2021
#>   most-flagged mediators:
#>     chi_che            1
#>     ext_usd2021_pc     1
#>     gge_gdp            1
#>     oops_che           1
#>     pvtd_usd2021       1
#>     shi_che            1
In 4 groups the benchmark p-value is above 0.05 (as high as 0.87), yet the power-enhanced test rejects, and its screen identifies a health-expenditure indicator as active, in each. The article’s Table 1 sets these rows in bold. Mediators whose effects differ in sign are one way this happens, because their contributions to the total indirect effect cancel.
(The small region-by-income cells contain indicators that are
constant within the cell. WHO_mediation_analysis() drops
those automatically; when calling pe_mediation() on such a
subset yourself, pass drop_constant = TRUE to do the
same.)
A Balanced Scorecard
| Situation | HDMM (benchmark) | PE (POEMED) |
|---|---|---|
| Null (no mediation) | size near 5% | size near 5%, slightly above the benchmark’s |
| Homogeneous mediation | powerful | powerful, with a margin |
| Heterogeneous: fully canceling | little power | much more power at the article’s design |
| Heterogeneous: partially canceling | weak | recovers the signal |
| Which mediators are active | not provided | identified, with asymptotic FWER or FDR control |
| Real-data subgroups | misses some | finds them |
The power-enhanced test’s size approaches the nominal level as the sample size and the number of candidate mediators grow, and in the article’s finite-sample tables it runs slightly above the benchmark’s. The test adds a margin where the benchmark is already strong and supplies power where the benchmark has little. That is the whole of the claim, and the rows above are the evidence for it.
Other Comparators
The article also benchmarks against HILMA (Zhou et al., 2020), GlobalTest (Djordjilović et al., 2019), and, for individual-mediator identification, HDMT (Dai et al., 2022) and DACT (Liu et al., 2022). Those methods live in their own packages, which POEMED does not depend on.
- HILMA is
hilma()in the packagefreebird. CRAN has archivedfreebirdbecause it depends on the archived packagescalreg, so installscalregand thenfreebirdfrom the CRAN archive. - GlobalTest is the Bioconductor package
globaltest, installed withBiocManager::install("globaltest"). - HDMT is the CRAN package
HDMT. - DACT: the package implementing the DACT method of Liu et al. is also
named
DACT, but it is not on CRAN and is instead available through their GitHub repository (remotes::install_github("zhonghualiu/DACT")). The CRAN package namedDACTis an unrelated clinical-trials package.
The chunk below runs HILMA and GlobalTest beside a POEMED fit on the same simulated data. It is not evaluated when this vignette is built, because POEMED does not depend on either package.
d <- simulate_mediation_data(n = 300, p = 500, outcome = "continuous",
                             pattern = "contrasting", c1 = 0.5)
pe <- pe_mediation(d$X, d$Y, d$M, outcome = "continuous")

# HILMA (package 'freebird'): a debiased-lasso total-mediation-effect test.
hilma_p <- freebird::hilma(d$Y, d$M, d$X)$pvalue_beta_hat

# GlobalTest (Bioconductor package 'globaltest'): a score test of the
# mediator block against the outcome.
gt_p <- globaltest::p.value(globaltest::gt(d$Y, d$M))

data.frame(method = c("HDMM", "PE-HDMM", "HILMA", "GlobalTest"),
           pval = c(pe$value[pe$term == "pval_hdmm"],
                    pe$value[pe$term == "pval_pe"], hilma_p, gt_p))
On contrasting data the total-indirect-effect methods (HDMM, HILMA)
both reject rarely, because both are built on the quantity that cancels.
At this design (c1 = 0.5), supplement Table S.4 gives
rejection rates over 1,000 replications of 0.087 for HDMM and 0.045 for
HILMA, against 0.331 for the power-enhanced test, so a single run may
not separate them. The article’s Figures 3 to 5 and supplement Tables
S.4 to S.6 report the comparison in full.
References
Yu, X., & Kelley, K. (in press). Power Enhancement in High-Dimensional Heterogeneous Mediation Analysis. Journal of the American Statistical Association.
Guo, X., Li, R., Liu, J., & Zeng, M. (2022). High-dimensional mediation analysis for selecting DNA methylation loci mediating childhood trauma and cortisol stress reactivity. Journal of the American Statistical Association, 117(539), 1110–1121. https://doi.org/10.1080/01621459.2022.2053136
Zhou, R. R., Wang, L., & Zhao, S. D. (2020). Estimation and inference for the indirect effect in high-dimensional linear mediation models. Biometrika, 107(3), 573–589. https://doi.org/10.1093/biomet/asaa016
Djordjilović, V., Page, C. M., Gran, J. M., Nøst, T. H., Sandanger, T. M., Veierød, M. B., & Thoresen, M. (2019). Global test for high-dimensional mediation: Testing groups of potential mediators. Statistics in Medicine, 38(18), 3346–3360. https://doi.org/10.1002/sim.8199
Dai, J. Y., Stanford, J. L., & LeBlanc, M. (2022). A multiple-testing procedure for high-dimensional mediation hypotheses. Journal of the American Statistical Association, 117(537), 198–213. https://doi.org/10.1080/01621459.2020.1765785
Liu, Z., Shen, J., Barfield, R., Schwartz, J., Baccarelli, A. A., & Lin, X. (2022). Large-scale hypothesis testing for causal mediation effects with applications in genome-wide epigenetic studies. Journal of the American Statistical Association, 117(537), 67–81. https://doi.org/10.1080/01621459.2021.1914634
Session Information
sessionInfo()
#> R version 4.6.1 (2026-06-24)
#> Platform: x86_64-pc-linux-gnu
#> Running under: Ubuntu 24.04.5 LTS
#>
#> Matrix products: default
#> BLAS:   /usr/lib/x86_64-linux-gnu/openblas-pthread/libblas.so.3
#> LAPACK: /usr/lib/x86_64-linux-gnu/openblas-pthread/libopenblasp-r0.3.26.so;  LAPACK version 3.12.0
#>
#> locale:
#>  [1] LC_CTYPE=C.UTF-8       LC_NUMERIC=C           LC_TIME=C.UTF-8
#>  [4] LC_COLLATE=C.UTF-8     LC_MONETARY=C.UTF-8    LC_MESSAGES=C.UTF-8
#>  [7] LC_PAPER=C.UTF-8       LC_NAME=C              LC_ADDRESS=C
#> [10] LC_TELEPHONE=C         LC_MEASUREMENT=C.UTF-8 LC_IDENTIFICATION=C
#>
#> time zone: UTC
#> tzcode source: system (glibc)
#>
#> attached base packages:
#> [1] stats     graphics  grDevices utils     datasets  methods   base
#>
#> other attached packages:
#> [1] POEMED_1.0.0
#>
#> loaded via a namespace (and not attached):
#>  [1] cli_3.6.6         knitr_1.52        rlang_1.3.0       xfun_0.61
#>  [5] otel_0.2.0        generics_0.1.4    textshaping_1.0.5 jsonlite_2.0.0
#>  [9] htmltools_0.5.9   ragg_1.5.2        sass_0.4.10       glmnet_5.1
#> [13] rmarkdown_2.32    grid_4.6.1        evaluate_1.0.5    jquerylib_0.1.4
#> [17] fastmap_1.2.0     foreach_1.5.2     yaml_2.3.12       lifecycle_1.0.5
#> [21] compiler_4.6.1    codetools_0.2-20  fs_2.1.0          Rcpp_1.1.2
#> [25] lattice_0.22-9    systemfonts_1.3.2 digest_0.6.39     R6_2.6.1
#> [29] ncvreg_3.16.0     splines_4.6.1     shape_1.4.6.1     bslib_0.12.0
#> [33] Matrix_1.7-5      tools_4.6.1       iterators_1.0.14  survival_3.8-6
#> [37] pkgdown_2.2.1     cachem_1.1.0      desc_1.4.3